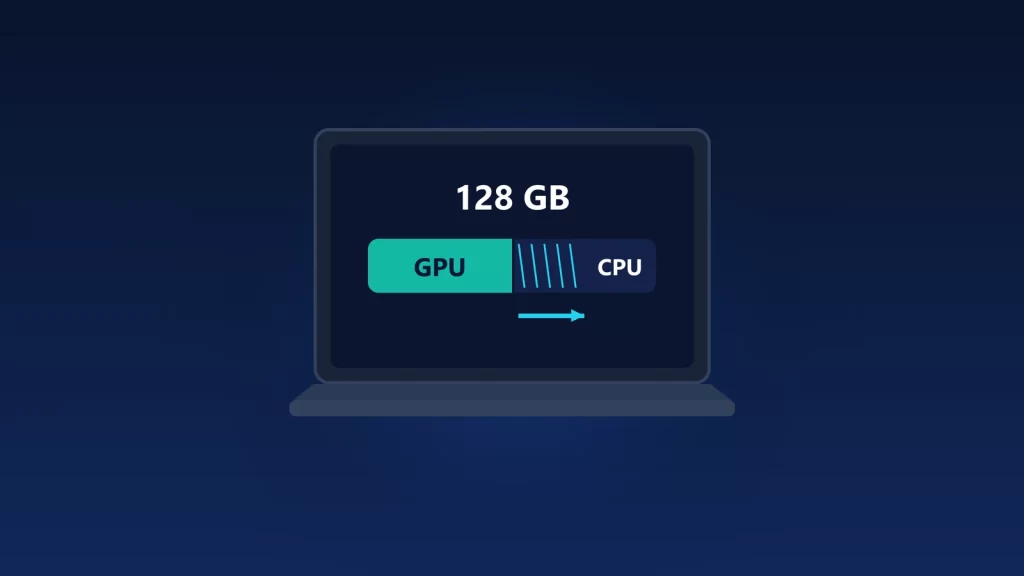
WSL 2 using too much memory? The real defaults, and what actually gives RAM back
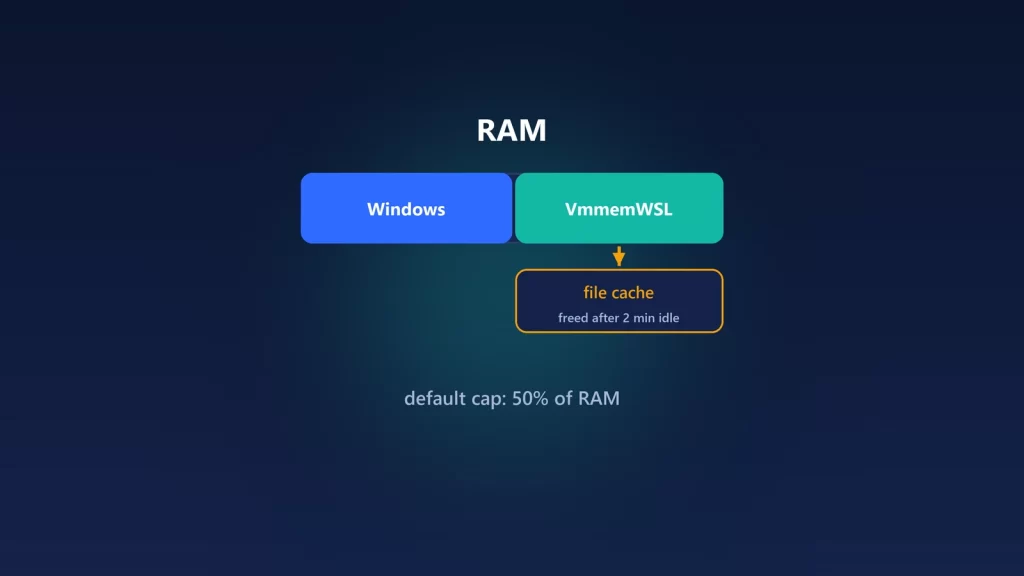
VmmemWSL can grow to half your RAM, and Linux file cache keeps it there. The real defaults from Microsoft's docs and WSL's code, how to cap memory, and why WSL…
Solo Tech Pros
Solo Tech Pros investigates, tests and builds with the technology changing how we work.
VmmemWSL can grow to half your RAM, and Linux file cache keeps it there. The real defaults from Microsoft's docs and WSL's code, how to cap memory, and why WSL…
Fresh coverage
Smart App Control blocks apps it can't verify and that aren't signed, with no per-app exceptions. Since March 2026 you…
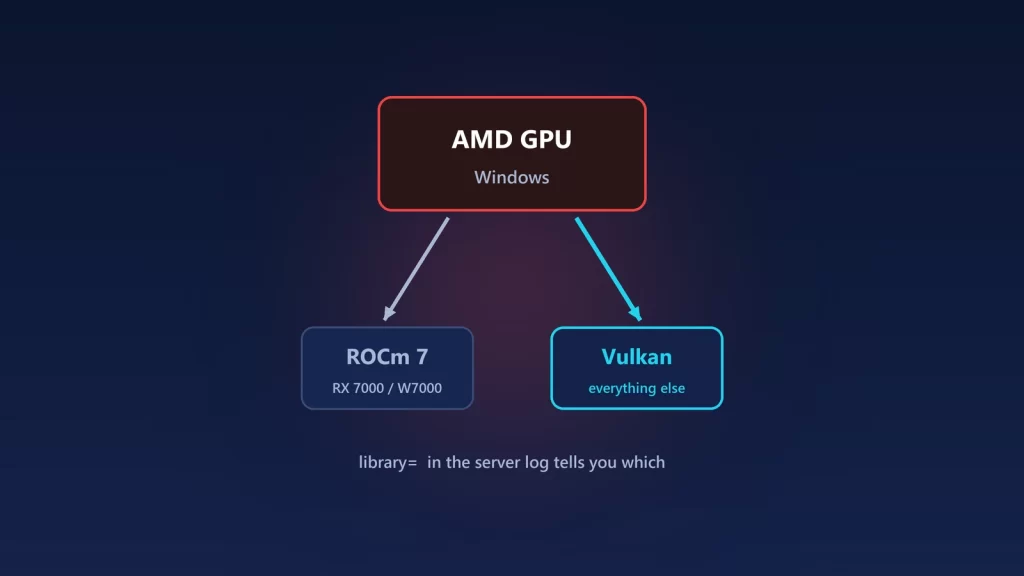
On Windows, Ollama uses ROCm only for Radeon RX 7000 and PRO W7000 cards. Everything else runs on Vulkan, which…
Windows uninstallers leave Foundry Local's downloaded models behind, and apps built on it keep their own caches. How to find…
Ollama uses a Modelfile's SYSTEM prompt only when a request has none, and Open WebUI often sends one, even from…
When Foundry Local lists only CPU models or an alias runs on the CPU, the NPU is rarely broken. Check…
Open WebUI's num_ctx overrides Ollama's own context setting, and a 2048 pre-fill is easy to miss. How to find which…
Browse by subject
AI and developer software, examined closely: coding agents, local model runtimes, MCP and the other ways AI tools…
Security for the way we work now: prompt injection and AI agent vulnerabilities, sandboxing for coding agents, supply-chain…
Guides and fixes for Windows PCs: local AI on Windows with Foundry Local, Windows ML and NPUs, plus…
The web and cloud services underneath everyday tools: cloud storage and accounts, how websites treat scripts, bots and…
Hardware for local AI and modern computing: AI PCs and laptops, NPUs and GPUs, and how much memory…